
Reference
Cloud benchmark evidence
This page reports live multi-region measurements against Cloudflare Workers and R2. Results describe the tested data, routes, regions, and time period. They do not establish database-wide superiority over another system.
Current-layout benchmark
The 25 September 2026 run measured the released snapshot, trie, read-bundle, and secondary-index paths after decoded-envelope hardening.
Tested production commit:
aaaf60ab263dd0165dd89205f83f9e54e2638277Raw artifacts:
- Complete JSON evidence
- Compact CSV summary
evidence/r2-current-layout-multiregion-2026-09-25.jsonevidence/r2-current-layout-summary-2026-09-25.csv
SHA-256:
JSON EE93073994C8D7917D203865DEC31C433F9D3DF77C56F44AC032904CB6DA0219
CSV  76210F31306CE6E7BF0E22C67BC498EA593634E08F89AD5A188A0F3D1B526DB9
Method
Disposable Node 22 containers ran in seven Azure regions:
| Azure caller region | Cloudflare colo |
|---|---|
| East US | IAD |
| West US 2 | PDX |
| North Europe | DUB |
| Southeast Asia | SIN |
| Japan East | NRT |
| Australia East | SYD |
| Brazil South | GRU |
Each caller used the production ThimbleDB browser read planner over HTTPS. Object retrieval, TDB1 decryption, bounded gzip decompression, caching, index planning, and result validation used the current package code. Writes ran inside the temporary Worker against R2.
The run used two independent replicates in every region and retained 3,808 measured operations. Warm-up operations are excluded.
This was not the production deployment. The Worker, R2 bucket, and Azure resource group were temporary and were deleted after evidence capture.
Data profiles
All profiles used the same deterministic JSON shape and two indexes:
- equality index on
category, coveringtitleandlastModified - range index on
lastModified, coveringtitleandcategory
| Profile | Documents | Decoded snapshot | Snapshot objects | Snapshot stored bytes | Trie objects | Trie stored bytes |
|---|---|---|---|---|---|---|
| Small | 128 | 51,536 | 4 | 7,281 | 121 | 37,414 |
| Medium | 5,000 | 2,037,420 | 4 | 233,984 | 276 | 351,875 |
| Large | 25,000 | 10,245,374 | 4 | 1,171,510 | 276 | 1,416,813 |
The object counts include HEAD, document data, and both secondary-index pages.
Cold point reads
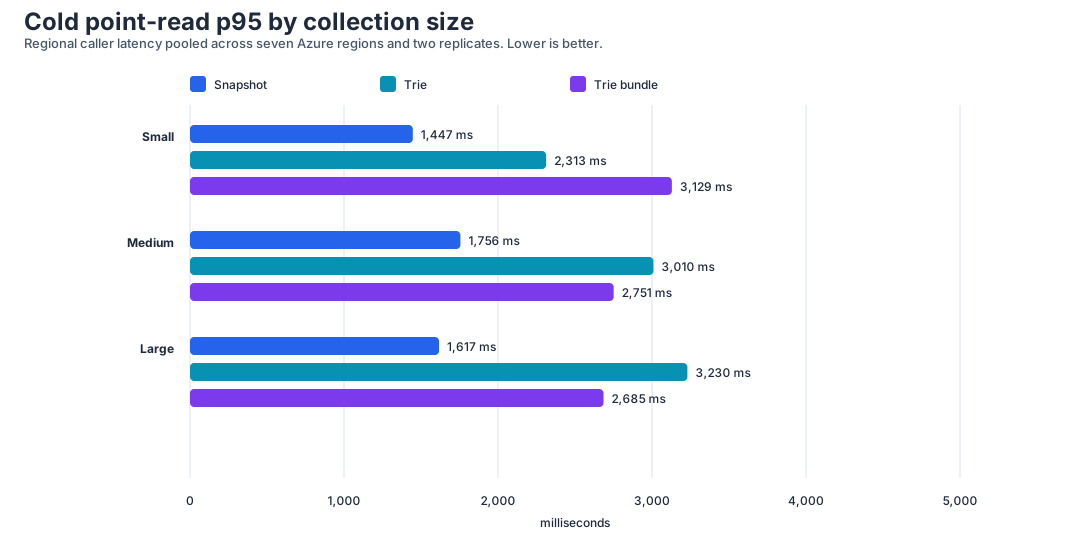
| Profile | Path | p50 | p95 | Success | Network reads | Network bytes | R2 reads | R2 bytes |
|---|---|---|---|---|---|---|---|---|
| Small | Snapshot | 374.86 ms | 1,446.86 ms | 168/168 | 2 | 2,944 | 2 | 2,944 |
| Small | Trie | 757.53 ms | 2,312.65 ms | 168/168 | 4 | 1,736 | 4 | 1,736 |
| Small | Snapshot bundle | 371.89 ms | 1,253.23 ms | 168/168 | 1 | 52,699 | 2 | 2,944 |
| Small | Trie bundle | 722.78 ms | 3,129.05 ms | 168/168 | 1 | 3,958 | 4 | 1,736 |
| Medium | Snapshot | 418.72 ms | 1,755.95 ms | 168/168 | 2 | 88,032 | 2 | 88,032 |
| Medium | Trie | 771.32 ms | 3,009.58 ms | 168/168 | 4 | 2,747 | 4 | 2,747 |
| Medium | Snapshot bundle | 509.54 ms | 1,452.58 ms | 168/168 | 1 | 2,038,593 | 2 | 88,032 |
| Medium | Trie bundle | 737.66 ms | 2,751.17 ms | 168/168 | 1 | 13,253 | 4 | 2,747 |
| Large | Snapshot | 642.08 ms | 1,617.18 ms | 168/168 | 2 | 448,462 | 2 | 448,462 |
| Large | Trie | 767.08 ms | 3,229.82 ms | 168/168 | 4 | 4,696 | 4 | 4,696 |
| Large | Snapshot bundle fallback | 836.03 ms | 2,475.30 ms | 167/168 | 3 | 448,462 | 4 | 896,924 |
| Large | Trie bundle | 719.78 ms | 2,685.03 ms | 168/168 | 1 | 45,868 | 4 | 4,696 |
Snapshot was the fastest direct point-read layout at every tested size. Compared with trie, snapshot p95 was:
- 37.44 percent faster for 128 documents
- 41.65 percent faster for 5,000 documents
- 49.93 percent faster for 25,000 documents
Trie transferred far fewer bytes, but four sequential network requests cost more than downloading and decoding Snapshot in this workload.
Trie bundle reduced four network requests to one. It improved trie p95 by 8.59 percent at 5,000 documents and 16.87 percent at 25,000 documents. It was 35.30 percent slower at p95 for 128 documents, where bundle assembly and JSON transfer outweighed the saved round trips.
Snapshot bundles were not a useful general optimisation:
- they transferred decoded JSON rather than the compressed TDB1 snapshot
- the medium bundle transferred about 2.04 MiB instead of 88 KiB
- the large bundle exceeded the 4 MiB decoded bundle limit and correctly fell back to individual object reads
One large snapshot bundle sample failed with a transport timeout. It remains in the raw evidence and is excluded from successful-operation percentiles.
Regional large point-read p95
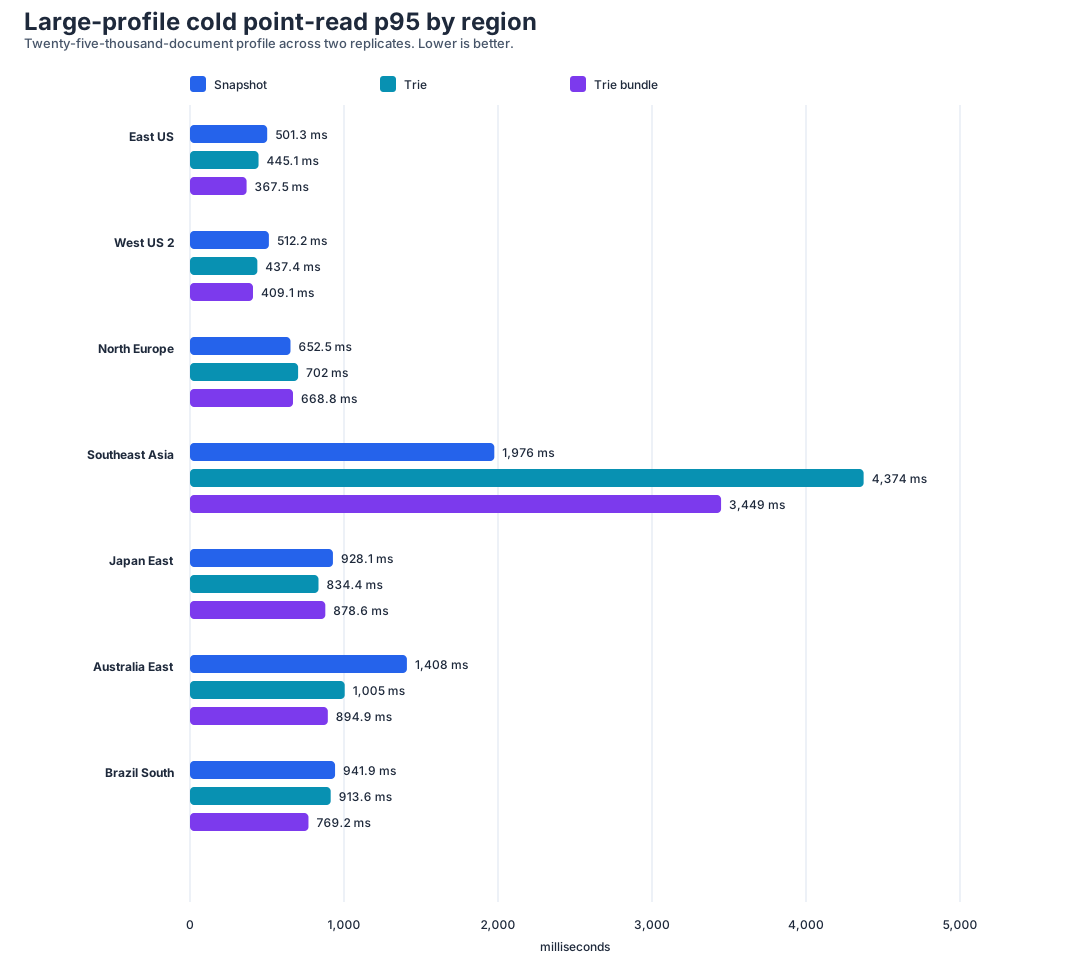
| Region | Snapshot | Trie | Trie bundle | Snapshot bundle fallback |
|---|---|---|---|---|
| East US | 501.28 ms | 445.10 ms | 367.47 ms | 560.51 ms |
| West US 2 | 512.22 ms | 437.38 ms | 409.05 ms | 604.50 ms |
| North Europe | 652.54 ms | 702.00 ms | 668.81 ms | 793.92 ms |
| Southeast Asia | 1,976.06 ms | 4,374.20 ms | 3,448.53 ms | 3,642.25 ms |
| Japan East | 928.12 ms | 834.41 ms | 878.64 ms | 1,137.97 ms |
| Australia East | 1,408.45 ms | 1,004.56 ms | 894.91 ms | 1,445.94 ms |
| Brazil South | 941.94 ms | 913.58 ms | 769.25 ms | 1,032.91 ms |
Regional results do not produce one universal winner. Snapshot had the better pooled p95, while trie or trie bundle won in several individual regions. Southeast Asia had the highest tail latency for every point-read path.
Secondary indexes
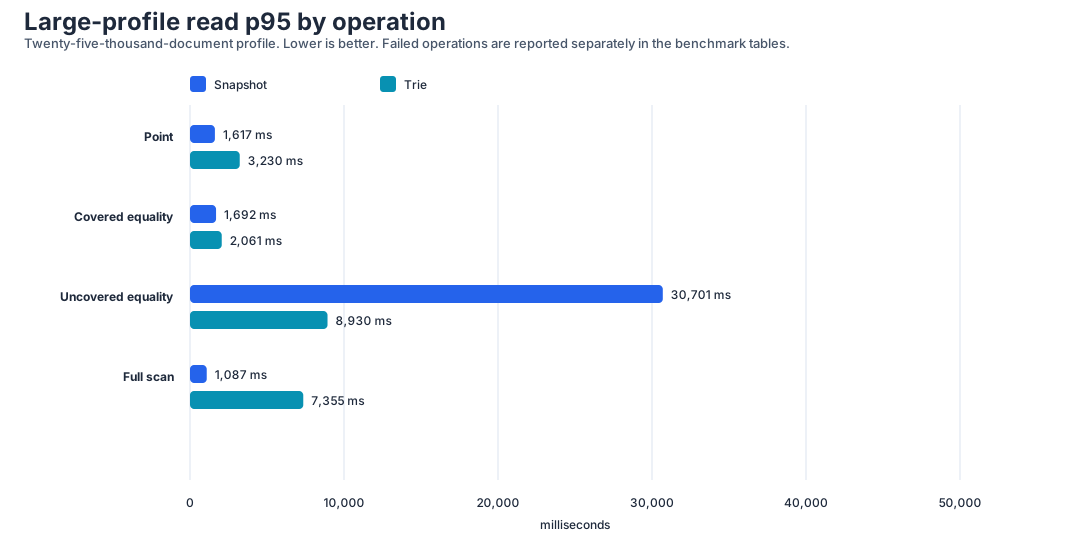
Covered equality
The query matched 0.5 percent of each collection and returned at most 25 documents entirely from the covering index.
| Profile | Snapshot p50 | Snapshot p95 | Trie p50 | Trie p95 | Network reads |
|---|---|---|---|---|---|
| Small | 377.73 ms | 1,371.21 ms | 379.81 ms | 1,563.82 ms | 2 |
| Medium | 465.04 ms | 1,886.27 ms | 428.14 ms | 1,123.80 ms | 2 |
| Large | 804.16 ms | 1,691.96 ms | 798.53 ms | 2,061.05 ms | 2 |
Layout choice made little difference because both paths read one HEAD and the same logical index page.
Uncovered equality
The same index selected candidate IDs, then the client loaded complete documents.
| Profile | Snapshot p50 | Snapshot p95 | Trie p50 | Trie p95 | Snapshot reads | Trie reads |
|---|---|---|---|---|---|---|
| Small | 579.27 ms | 2,261.58 ms | 945.36 ms | 3,732.84 ms | 3 | 5 |
| Medium | 1,080.95 ms | 3,475.87 ms | 1,118.78 ms | 6,308.08 ms | 3 | 36 |
| Large | 17,994.23 ms | 30,700.95 ms | 1,996.24 ms | 8,929.58 ms | 3 | 117 |
Large Snapshot behavior is a clear rejection boundary. It used only three network reads, but repeatedly handled a cached 10.25 MiB snapshot while materialising 125 candidates. The benchmark does not separately isolate structured-clone, lookup, filtering, and garbage-collection time, so it does not assign the delay to one browser-client operation.
At this size, Trie was much faster for the uncovered selective query even with 117 network reads. A covering index remained substantially faster than either full-document path:
- 95.53 percent faster at p50 than the large-profile Snapshot uncovered query
- 60.00 percent faster at p50 than the large-profile Trie uncovered query
Covered range
The range returned 25 documents from covering index fields.
| Profile | Snapshot p50 | Snapshot p95 | Trie p50 | Trie p95 | Index candidates |
|---|---|---|---|---|---|
| Small | 384.38 ms | 1,990.83 ms | 374.21 ms | 1,583.73 ms | 39 |
| Medium | 473.98 ms | 1,612.96 ms | 510.99 ms | 1,919.19 ms | 1,500 |
| Large | 1,044.55 ms | 2,115.30 ms | 1,026.00 ms | 2,018.80 ms | 7,500 |
Current range planning selected every value above the lower bound before applying the upper bound, so the 25-document large result evaluated 7,500 index candidates. Covering fields still kept the operation to two network reads and avoided loading document pages.
Full scans
| Profile | Snapshot p50 | Snapshot p95 | Snapshot success | Trie p50 | Trie p95 | Trie reads | Trie success |
|---|---|---|---|---|---|---|---|
| Small | 376.38 ms | 1,701.38 ms | 28/28 | 1,100.53 ms | 6,163.25 ms | 119 | 28/28 |
| Medium | 434.50 ms | 2,143.41 ms | 28/28 | 1,979.30 ms | 11,090.79 ms | 274 | 27/28 |
| Large | 645.52 ms | 1,086.59 ms | 28/28 | 2,007.04 ms | 7,354.85 ms | 274 | 26/28 |
Snapshot p95 was 72.39 to 85.23 percent faster than trie. Three trie scan samples failed with client transport timeouts and remain in the evidence.
Snapshots remain the correct current layout for scan-heavy collections.
Writes
The write workload updated one document in the 25,000-document indexed collection. Each of seven regional callers used its own collection, so these measurements do not contain cross-region conflicts.
| Layout | p50 | p95 | Success | R2 reads | R2 writes | Mean bytes written | CAS retries |
|---|---|---|---|---|---|---|---|
| Snapshot | 5,596.32 ms | 16,754.83 ms | 112/112 | 4 | 3 | 810,653 | 0 |
| Trie | 6,438.56 ms | 20,177.48 ms | 112/112 | 8 | 5 | 366,265 | 0 |
Snapshot wrote 121.33 percent more bytes, but was 13.08 percent faster at p50 and 16.96 percent faster at p95. With two global secondary indexes, object round trips outweighed lower Trie byte count in this test.
This does not mean snapshot writes scale indefinitely. Snapshot write bytes still grow with the collection. Current indexes materially change the write comparison and must be included in layout decisions.
Simultaneous multi-region writes
Seven callers started five snapshot updates and five trie updates against the same large collection generation in each of two replicates.
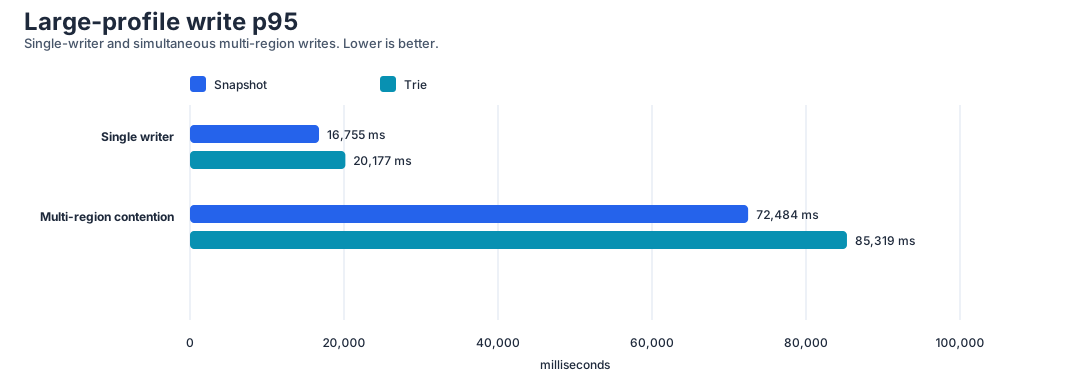
| Layout | p50 | p95 among successes | Success | Mean CAS retries | Mean R2 reads | Mean R2 writes |
|---|---|---|---|---|---|---|
| Snapshot | 11,332.98 ms | 72,483.54 ms | 66/70, 94.29% | 1.621 | 10.485 | 8.273 |
| Trie | 14,356.41 ms | 85,319.01 ms | 69/70, 98.57% | 2.217 | 25.739 | 11.246 |
Four Snapshot failures were Cloudflare 503 responses after long requests. Trie had one R2 internal write error. Failed operations are not included in the latency percentiles.
Both layouts are poor fits for sustained globally contended writes. The retry protocol preserved successful updates, but latency and availability degraded far beyond a reasonable interactive target.
Envelope limit validation
Every one of the 14 regional read runs fetched a 16,336-byte gzip envelope whose decoded payload was 16,777,217 bytes. All 14 rejected it at the 16,777,216-byte limit.
This validates the hardened decompression path in the Cloudflare Worker runtime. The benchmark does not claim that the 16 MiB default is suitable for every application. It is the supported normal-object boundary for ThimbleDB’s small-app target.
Current recommendation
Most measured cold reads and every large write result exceed normal interactive latency targets. Current production use therefore depends on warm browser cache hits dominating user activity. Cold storage access should be treated as initial loading, recovery, or background work rather than a request-critical UI path.
Use snapshots for:
- small and medium collections
- full scans
- reference data
- low write rates
- the lowest object-request count
Use tries when:
- selective full-document queries would repeatedly process a large snapshot
- lower transfer volume matters more than request count
- collection growth makes snapshot rewrite bytes unacceptable
- measured contention and latency remain within the application’s limits
Use covering indexes whenever a query can be satisfied from declared fields. The large covered equality query avoided the 8.9 to 30.7 second p95 measured for the corresponding uncovered paths.
Do not use either current layout for sustained multi-region writes to one collection root.
Do not use the current release for latency-sensitive applications that require sub-second cold reads or interactive large indexed writes.
Limitations
- Azure regions approximate geography and do not represent residential last-mile networks.
- Node 22 ran the production browser read planner, but the benchmark did not measure Chromium scheduling, IndexedDB, or rendering.
- Authentication and key-grant latency were excluded.
- One Cloudflare account and one R2 bucket placement were used.
- Successful-operation percentiles exclude the explicitly reported failed operations.
- Cloudflare and network conditions vary over time.
- Costs were not measured.
- These results compare ThimbleDB layouts with each other, not with another database.
Historical authenticated browser run
The 24 September 2026 artifacts remain available:
evidence/r2-browser-multiregion-trie-2026-09-24.json
evidence/r2-browser-multiregion-snapshot-2026-09-24.json
That run used Chromium 153, a production custom domain, real Entra session exchange, three Azure regions, a 128-product catalogue, and a 32-customer scan. It established:
- warm in-memory snapshot p95 of 1.6 to 8.3 ms
- snapshot cold-read improvement of 29 to 53 percent over trie
- materially slower cold reads and external session creation
The historical browser measurements and the current temporary-Worker measurements use different workloads and should not be compared as a single time series.